Connect Kubernetes
Add a cluster, install the Costfluent agent into it with Helm and the cluster token, and see its cost by cluster, namespace and label.
Costfluent distributes the cost of a Kubernetes cluster's nodes across namespaces and shows the remaining idle cost. It does not offer a verified per-pod, workload or container cost view. A small agent, installed with Helm, reads resource usage inside the cluster and reports it to Costfluent every hour. You add the cluster first, under Settings, then Integrations, then Kubernetes, on the Connect tab, and the agent reports with that cluster's token.
How Costfluent connects
The agent only reads: nodes, pods, persistent volumes and storage classes, the ReplicaSets and Jobs that own pods, the resource metrics each kubelet serves, and, only when you allow it, namespaces and persistent volume claims. It reads kubelet metrics with the token of a second service account that can read nothing but node metrics: the agent may create a token only for that account, requests one valid for an hour at a time, and never sends its own token to a kubelet. It sends each report's cluster ID, agent version, random instance ID and window, node shape, identity, labels and GPUs, the node and storage class annotations described below, pod and container identity, resource requests and usage, how many nodes it could not read and why, every pod label unless you limit them, the pod annotations you allow, namespace and claim labels when you allow them, the claims each pod mounts, and each persistent volume's size, storage class, driver, phase, claim and, for an AWS, Azure or GCP disk, the disk's id. It never sends container images, environment variables, secrets, config maps, volume contents, logs or network traffic. The chart README's table of what the agent reads and sends is the complete list.
Reports that cannot be delivered are kept on the agent's volume, for up to 96 hours and 50 MB, and sent once Costfluent is reachable again. A day that receives reports after it was processed is processed again from all of its reports: by the third night after the day, or by the night after the reports arrive when that is later.
Prerequisites
- A Kubernetes cluster you can install a Helm chart into, with cluster-wide read access for the agent's service account.
- A default StorageClass for the agent's 1 GiB volume, or install with
persist=null(Key values). - Outbound HTTPS from the cluster to
https://api.costfluent.com, directly or through a proxy. - The Owner or Integration owner organization role in Costfluent, the roles that manage data sources.
Connect
Install the agent
The Connect tab on the Kubernetes page holds the same steps with commands to copy, and so does onboarding's Connect step when you choose Kubernetes (Quickstart).
-
On the Connect tab, choose Add cluster and give it a cluster ID. The ID identifies the cluster in Costfluent and must be unique within your organization: 1 to 63 letters, digits, dots, underscores or hyphens, starting with a letter or digit. It cannot be changed later, since cost reports group the cluster's cost by it. A Display name is optional: it names the cluster's connection everywhere Costfluent shows it, and without one the cluster ID does. Rename, in the cluster's row menu or on its page, changes it later. Rename needs a name: to name the connection by the cluster ID again, type the cluster ID. An organization holds up to 100 clusters.
-
Costfluent shows the cluster token once, with the install command that carries it. The token reports usage for this cluster and nothing else: it cannot report another cluster or read any data. Copy it now.
-
Read the token into
COSTFLUENT_CLUSTER_TOKEN: paste it at the silent prompt and press Enter, so it never sits in a command line or your shell history. Then install the chart:Code
A cluster token works on every plan. New token in a cluster's row menu issues another token for it, for a new install or to replace one that leaked; revoke the old one under Settings, then API tokens.
Install one agent per cluster. The cluster shows as Pending until the first report, a few minutes after the agent starts, and then as Importing. A new cluster feeds no workspace yet: the token dialog ends with Choose workspaces, which opens the cluster's page, where you choose the workspaces that should see its cost, as the section after Sizing shows. A cluster added on the Connect tab opens that page when you close the token dialog, too.
The console's install command first asks where the cluster runs and adds what that cluster needs:
on AKS agent.nodeAddressTypes=InternalIP, because its kubelets are often not reachable at their
default address; on OpenShift podSecurityContext.runAsUser, runAsGroup and fsGroup set to
null, so OpenShift assigns the namespace's own user IDs; and for Talos, kubeadm or kind
agent.disableKubeTLSverify=true (Kubelet certificates). For EKS, GKE,
k3s, RKE2 and other clusters it adds nothing and keeps kubelet certificate verification on. When the
agent cannot read some nodes' kubelets, the cluster turns Warning after its first report and its
Cluster health card names the fix (Common errors). A cluster without a cloud bill also needs
node rates before its usage is priced.
Key values
| Value | Default | Purpose |
|---|---|---|
agent.token | none | The cluster token. Set it, or agent.secret. |
agent.secret.name, agent.secret.key | none, token | An existing Secret holding the token, and the key in it, instead of agent.token. |
agent.clusterID | the token's cluster | Optional. When set, the agent refuses to start unless it is the token's cluster. |
agent.apiEndpoint | https://api.costfluent.com | Where reports go. |
agent.pollingInterval | 60 | Seconds between usage samples: 5, 10, 15, 30 or 60. |
agent.nodeAddressTypes | InternalIP,InternalDNS,Hostname,ExternalIP,ExternalDNS | Which node addresses the agent tries, in order, to reach each kubelet. |
agent.disableKubeTLSverify | false | Skip verifying kubelet certificates. |
agent.allowedLabels | all | Pod labels to send. Empty sends every pod label. |
agent.allowedAnnotations | none | Pod annotations to send, at most 10. Empty sends none. |
agent.collectNamespaceLabels | false | Send namespace labels. |
agent.collectPVCLabels | false | Send each bound volume's claim labels, which lets the agent list persistent volume claims. |
agent.reportHTTPProxy | none | An HTTP proxy for the upload, without credentials. |
agent.reportHTTPProxySecret.name, agent.reportHTTPProxySecret.key | none, none | An existing Secret and the key in it holding the upload proxy's URL, credentials included, instead of agent.reportHTTPProxy. |
agent.reportCABundle.configMap, agent.reportCABundle.secret, agent.reportCABundle.key | none, none, ca.crt | An existing ConfigMap or Secret, one of the two, and the key in it holding PEM certificates the agent trusts for the upload, for a proxy that re-signs TLS. |
agent.logLevel | info | How much the agent logs. |
persist | a volume claim | null keeps the buffer in an emptyDir instead, for a cluster without a StorageClass; it is lost when the pod is rescheduled. |
persist.size | 1Gi | The volume that buffers reports while Costfluent cannot be reached. |
persist.storageClassName | the cluster's default | The storage class of that volume. |
resources | requests 50m CPU and 64Mi, limit 256Mi | CPU and memory requests and limits for the agent. |
Keep the token out of your values files in source control: store it in a Secret and point
agent.secret at it.
Kubelet certificates
The agent reads each node's usage from its kubelet on port 10250 and verifies the kubelet's serving certificate. The console's command keeps verification on for EKS, GKE, k3s, RKE2 and other clusters, and k3s kubelets pass it. Talos, kubeadm and kind kubelets serve self-signed certificates by default, and every read fails until one of these holds:
- The kubelets serve certificates the cluster CA signs, and verification stays on. On kubeadm, set
serverTLSBootstrap: truein the kubelet configuration and approve the kubelets' certificate signing requests; on Talos, set the kubelet'srotate-server-certificatesargument totrueand run an approver for those requests. This is the secure fix. - The agent skips verification with
agent.disableKubeTLSverify=true, which the console's command for Talos, kubeadm or kind sets. Whatever answers on a node's port 10250 is then trusted: it receives the agent's kubelet token, which can read node metrics and nothing else, and could feed the agent false usage.
The kubelet token protects only kubelets that check it. A kubelet whose webhook authentication is off and that allows anonymous requests serves its metrics to any caller that reaches port 10250, with or without the agent; that exposure is the cluster's own, and no agent setting changes it.
GitOps with Argo CD or Flux
Argo CD or Flux can install the agent from the chart repository. The token goes into a Secret
that agent.secret.name and agent.secret.key name, so no manifest in your repository holds it.
The Connect tab and the token dialog offer GitOps beside Helm: once you choose where the
cluster runs, they show the Secret command and both manifests, with the values that cluster needs
and the newest chart version filled in.
-
With the cluster as kubectl's current context, read the token at the silent prompt and store it in a Secret in the agent's namespace. The namespace line fails harmlessly when it exists already.
Code -
Commit one manifest to the repository your controller syncs. For Argo CD, an
Applicationin the namespace Argo CD runs in, which syncs as your other applications do, by hand or automatically:CodeFor Flux, a
HelmRepositoryand aHelmReleasein the agent's namespace:Code
Both install the release as cfa in the costfluent namespace, as the install command does, so
the names and labels this page's kubectl commands use are the same. Add under the values what the
console's install command sets for where the cluster runs (Install the agent),
such as agent.nodeAddressTypes on AKS.
This page's helm commands do not work on a GitOps install. Argo CD renders the chart and applies
what it renders, so the cluster holds no Helm release, and helm upgrade or helm uninstall of
cfa finds none. Flux keeps a Helm release, but its next reconcile puts the release back to the
HelmRelease, so a value set by hand does not last. Change the install through its manifest:
-
A value. Set it under
valuesObjectorvaluesand commit it. A fix the Cluster health card or this page gives as--set key=valuegoes there too, askey: valueunder its parents. -
Update. Each manifest pins one chart version, never a range, so a new chart reaches the cluster only once you set it. The examples pin the chart this page documents; the console's manifests pin the newest. Set
targetRevisionorversionto the chart version that Update the agent on the Manage tab names, and commit it. -
Token. The token sits in the
costfluent-tokenSecret, which neither controller manages: replace it and restart the agent with theagent.secretcommands of Rotate the token. -
Disconnect. On Argo CD, remove the
Applicationfrom your repository so nothing recreates it, and delete it with its resources:argocd app delete costfluent-agent. Akubectl deleteof theApplicationremoves the agent only when the Application carries theresources-finalizer.argocd.argoproj.iofinalizer; without it the agent keeps running. On Flux, remove theHelmReleaseand theHelmRepositoryfrom your repository: Flux deletes them where its Kustomization prunes, otherwisekubectl -n costfluent delete helmrelease costfluent-agentdoes, and deleting theHelmReleaseuninstalls the release. With either, then delete the claim the StatefulSet left and the token's Secret, and remove the connection as Disconnect describes:Code
Flux waits for the agent to become ready after an install, as the install command's --wait does.
Argo CD renders the chart offline, so the chart's StorageClass check does not run there
(Self-hosted clusters).
Private and self-hosted clusters
The agent runs inside the cluster. It needs DNS, the Kubernetes API server, each node's kubelet on
port 10250 and outbound HTTPS to api.costfluent.com, directly or through a proxy; Costfluent
never connects to it. A cluster that cannot reach Costfluent at all, even
through a proxy, cannot be connected.
Private managed clusters
An EKS, AKS or GKE cluster with a private API endpoint needs nothing more: the agent reaches the
API server from inside the cluster. The nodes need outbound HTTPS to api.costfluent.com, through
a NAT gateway or a proxy (Egress proxy). Run the install command from wherever
kubectl reaches the cluster, such as a bastion host or a runner in its network, or let a GitOps
controller in the cluster install the chart, with the token in a Secret that agent.secret.name
names (GitOps with Argo CD or Flux).
Egress proxy
The agent sends its traffic to Costfluent, its reports and its token check at start, through the
proxy you name, and never sends Kubernetes API or kubelet traffic through it. The proxy must let
the agent open a tunnel to api.costfluent.com on port 443. Name a proxy without credentials in
agent.reportHTTPProxy; the chart refuses a URL with a user or password there, so put such a URL
in a Secret and name it in agent.reportHTTPProxySecret:
Code
A proxy that inspects TLS re-signs Costfluent's certificate with its own CA, which the agent does
not trust by default. Put that CA's PEM certificates in a ConfigMap, or in a Secret with
kubectl create secret generic, and name it in agent.reportCABundle. The agent trusts them
beside the public CAs, for its traffic to Costfluent only, never for the Kubernetes API server or
the kubelets:
Code
Then install with the proxy's values beside the token, here a proxy with credentials and its CA:
Code
A proxy without credentials takes --set agent.reportHTTPProxy=http://proxy.internal:3128 instead
of the two agent.reportHTTPProxySecret lines, and a CA in a Secret takes
agent.reportCABundle.secret instead of agent.reportCABundle.configMap. The key in either
defaults to ca.crt; set agent.reportCABundle.key for another.
Default-deny egress
Where a NetworkPolicy denies egress by default, allow the agent's pod these flows:
- DNS, to the cluster's DNS service.
- The Kubernetes API server, at the address and port its endpoints name (
kubectl get endpointslices -n default -l kubernetes.io/service-name=kubernetes). - Each node's kubelet, on port 10250, at the address
agent.nodeAddressTypespicks. - Port 443 of
api.costfluent.com, or the proxy's address and port when the agent uses one.
api.costfluent.com is served through Cloudflare, so its addresses are shared and change, and an
IP rule cannot name it. Where the agent uses a proxy, allow only the proxy. Without one, use your
CNI's rule for a domain name, below; only a CNI without one leaves port 443 to any address. This
example, for the release cfa, allows a proxy; replace the addresses with your cluster's:
Code
The second rule is the API server's endpoint, the third the node network the kubelets listen on,
and the last the proxy. Without a proxy and without a domain rule, the last rule allows
0.0.0.0/0 on port 443 instead.
The first rule fits kube-dns or CoreDNS pods in kube-system that listen on port 53. Two other DNS
setups need their own rule in its place. NodeLocal DNSCache answers on each node itself, at its
local address and, in iptables mode, at the DNS Service's address too, not from the DNS pods, so
allow those addresses with an ipBlock on port 53. OpenShift's DNS pods run in the openshift-dns
namespace and listen on port 5353 behind the Service's port 53, so select that namespace and allow
UDP and TCP on port 5353.
CNIs match the API server and the kubelets, which listen on the nodes' own network, differently.
Most apply a NetworkPolicy after the kubernetes Service's address is translated to the API
server's, so a rule names the endpoint, not the Service. Cilium's ipBlock does not match nodes
or the API server unless Cilium runs with --policy-cidr-match-mode=nodes; allow them with its
entities instead, as the Cilium example below does. When the agent's log reports kubelets or the
API server unreachable after you apply a policy, check how your CNI selects them.
On Cilium, a CiliumNetworkPolicy names the API host with toFQDNs. Cilium learns its addresses
from the DNS answers it inspects, so the policy also allows DNS through its DNS rule:
Code
On Calico Cloud or Calico Enterprise, a Calico NetworkPolicy names it with destination.domains,
in place of the NetworkPolicy's last rule; the NetworkPolicy's DNS rule stays:
Code
Private registry
The agent image, ghcr.io/costfluent/k8s-agent, is built for amd64 and arm64, and the chart pulls
it by the digest its release resolved. Mirror it with a copy that keeps both architectures and the
digest, such as crane copy or skopeo copy --all --preserve-digests, under the tag of the
chart's appVersion, which helm show chart costfluent/costfluent-k8s-agent --version <chart-version>
shows for the chart version the install command below pins:
Code
Then install with image.repository set to the mirror and, when the registry needs credentials,
an existing pull Secret in imagePullSecrets:
Code
The chart's image.digest wins over image.tag, and still matches the mirror only when the copy
kept the digest. A copy that rebuilt the image, or a registry that rewrote it, needs image.digest
set to the mirror's digest, or set to "" to pull by tag.
OpenShift
OpenShift's default security context constraint, restricted-v2, gives each namespace its own
range of user IDs and assigns the pod one from it. The chart asks for user and group 1000, so on
OpenShift install with those IDs cleared, which the console's command for OpenShift adds:
Code
The pod still runs as a user other than root, with the runtime's default seccomp profile.
Self-hosted clusters
- Kubelet certificates. The secure fix is kubelet serving certificates the cluster CA signs;
agent.disableKubeTLSverify=truecomes second, with what it trusts (Kubelet certificates). - Node addresses. For each node the agent takes the first address of the types
agent.nodeAddressTypeslists, in order, that the node has, and does not try the next one when it cannot connect. When a node's first address of those types is on a network pods cannot reach, list the type they can reach first, such asagent.nodeAddressTypes=ExternalIP,InternalIP. - Storage. The agent's buffer needs a StorageClass that provisions its volume claim: set
persist.storageClassName, or install withpersist=nullfor an emptyDir. Argo CD renders the chart withhelm template, without reading the cluster, so the install's StorageClass check does not run there and a claim no class provisions stays Pending. - Node rates. Nodes no cloud bills are priced from the rates you set (On-premises and custom rates); until then they are left out and counted as unpriced.
Sizing
The agent is one pod, whatever the size of the cluster. Its memory grows with the number of
containers it tracks. Measured with 61 pods at a 5 second polling interval, its working set
averaged 11.4 MiB with a 12.8 MiB peak, using under 0.001 CPU cores. The defaults (64Mi
requested, 256Mi limit) leave room for clusters many times that size; raise the memory limit if
the pod is restarted for exceeding it.
Costfluent collects clusters of up to 1,000 nodes and 50,000 pods. A larger cluster's reports are refused (see 400 under Common errors). Persistent volumes never refuse a report: past 50,000 the agent sends the first by name, and a pod mounting more than 32 claims sends its first 32.
One cluster day keeps up to 50,000 containers in detail. Containers that start later that day, as a CronJob's pods do, are counted together by workload on each node, then by namespace on each node; past those, a container's usage is not counted and stays in its node's idle cost, so the day still holds all of its nodes' cost. A container or node keeps up to 64 labels, the first by key. The cluster then shows Warning, and the line under the status says what was grouped. A day with more than 20,000 node instances is not processed, and the line under the status says why. A cluster day keeps up to 1,440 reports, which an agent reaches only when it restarts hundreds of times that day; past them, a new window of that day is refused (see 409 under Common errors), a window the day already holds is accepted again, and the day is processed with the reports it keeps. A day prices up to 25,000 persistent volumes and keeps 50,000 pods' mounts of a claim apart; past those, a pod's mounts are counted with its workload's, then left to the claim's namespace, and a volume past the cap is not counted, which the line under the status also says.
An organization's clusters send at most 1 GiB of compressed reports a UTC day together, each report counted on the day it arrives. Past it, a report is refused until midnight UTC (see 429 under Common errors). The agent keeps the refused report and those after it, and sends it again at least every 15 minutes, so they arrive soon after midnight, unless the agent's buffer fills first and drops its oldest reports.
Choose which workspaces see a cluster
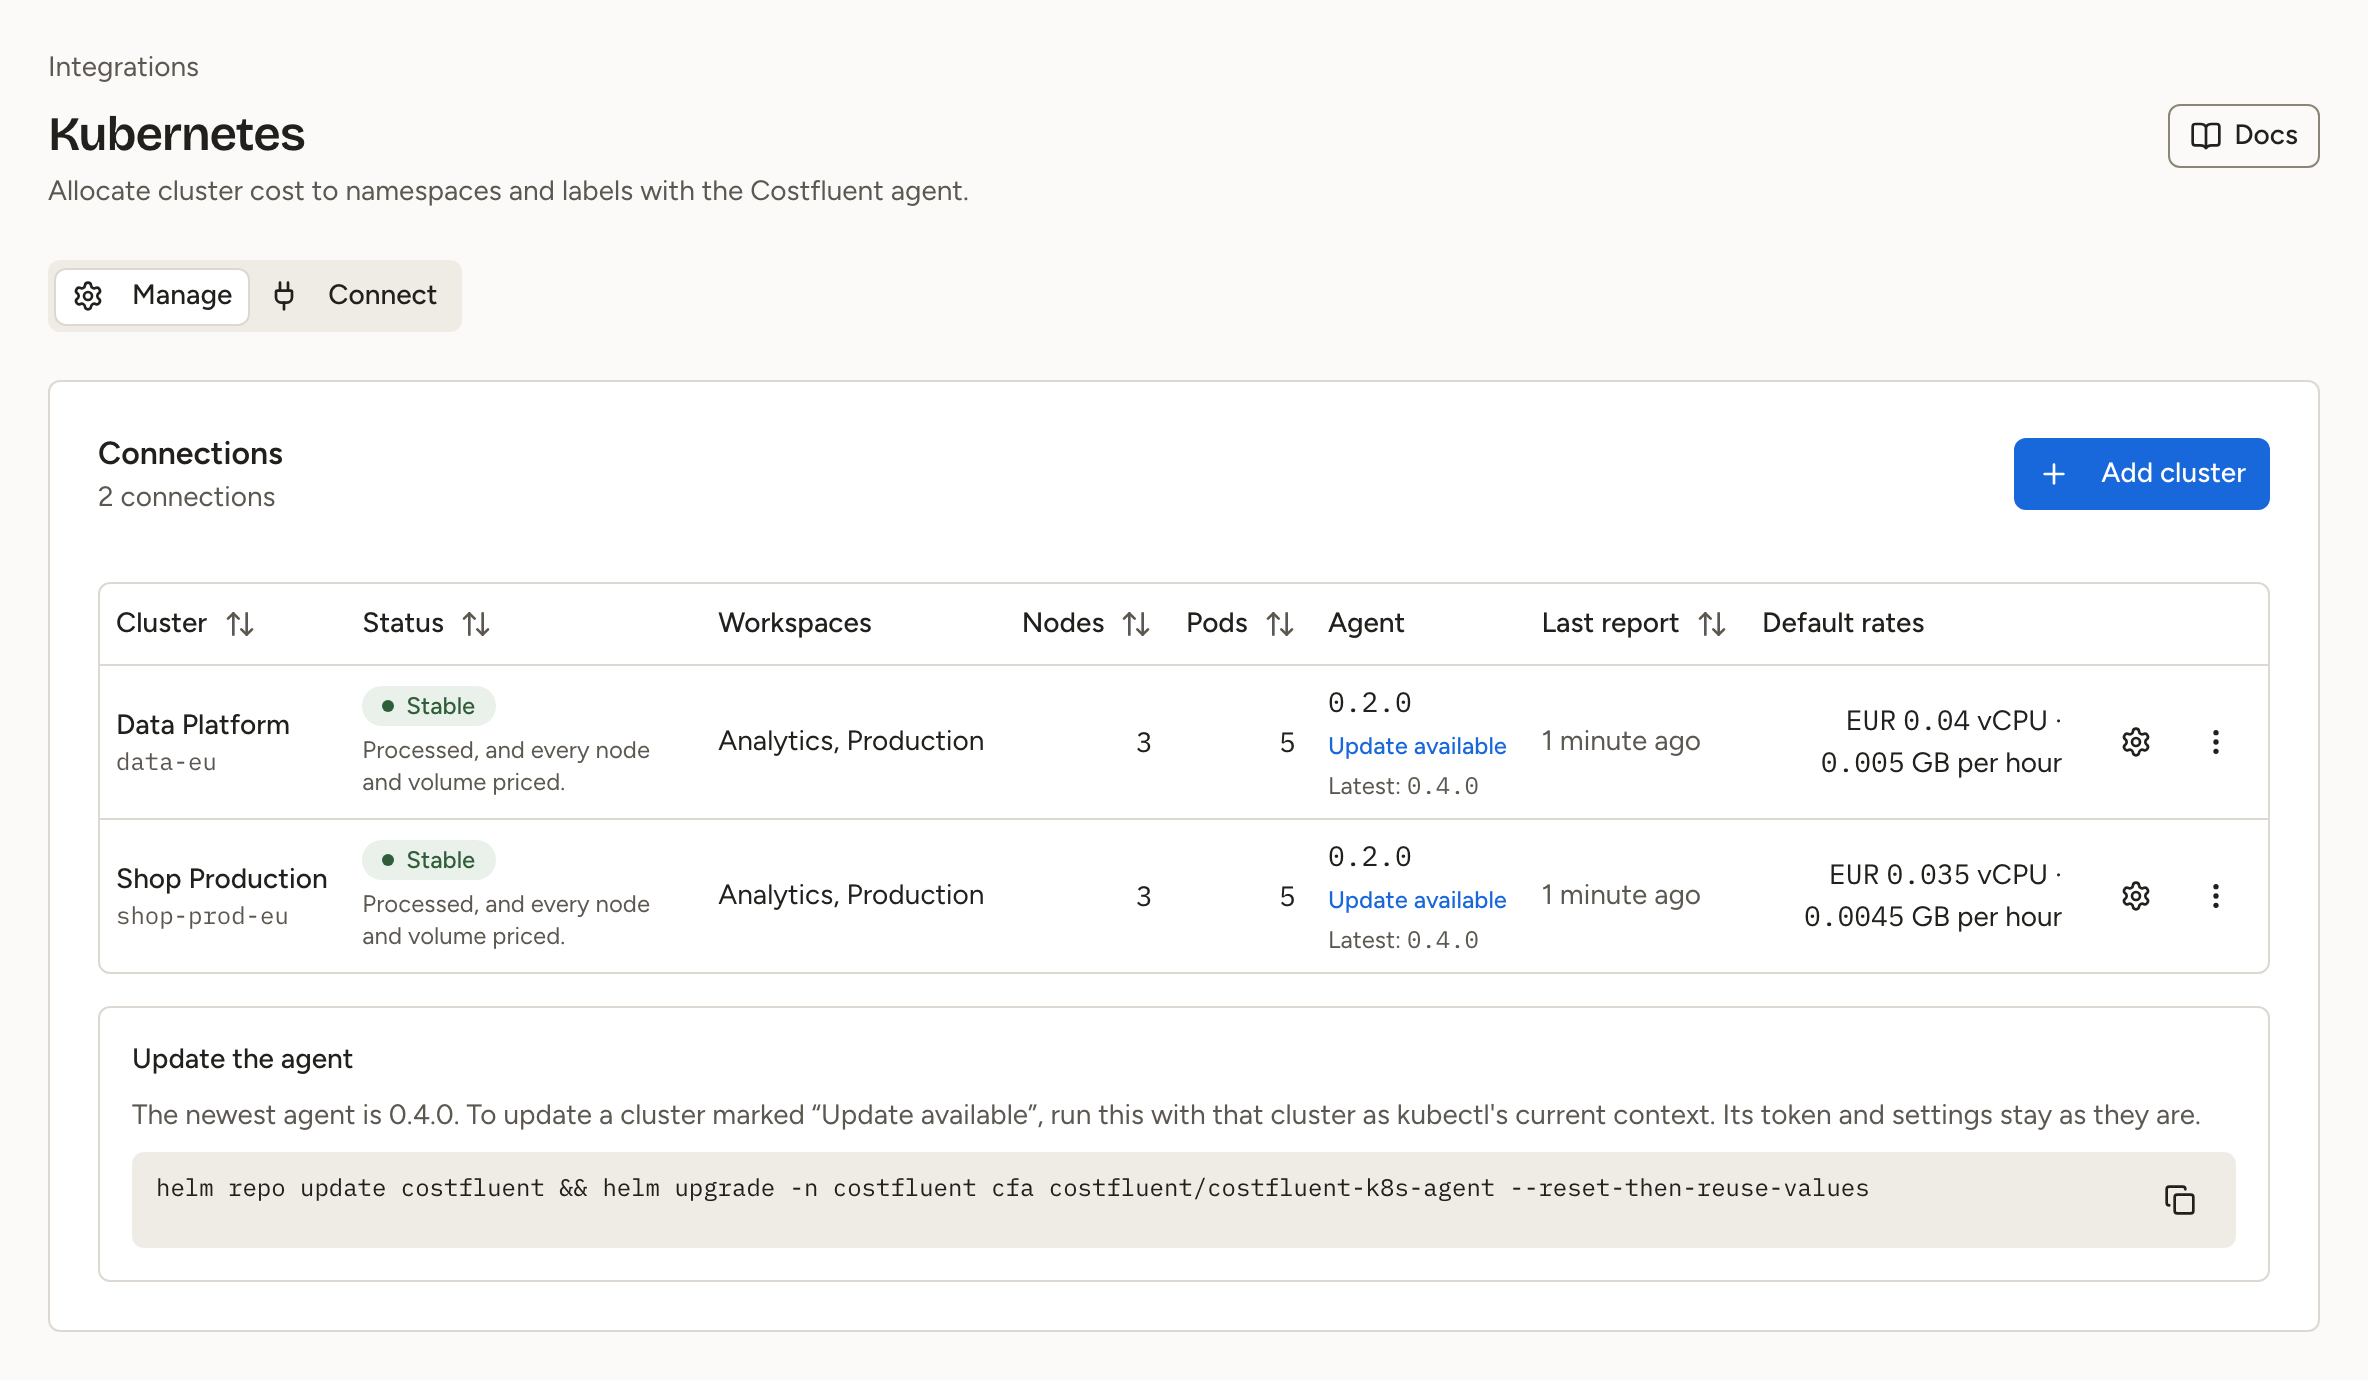
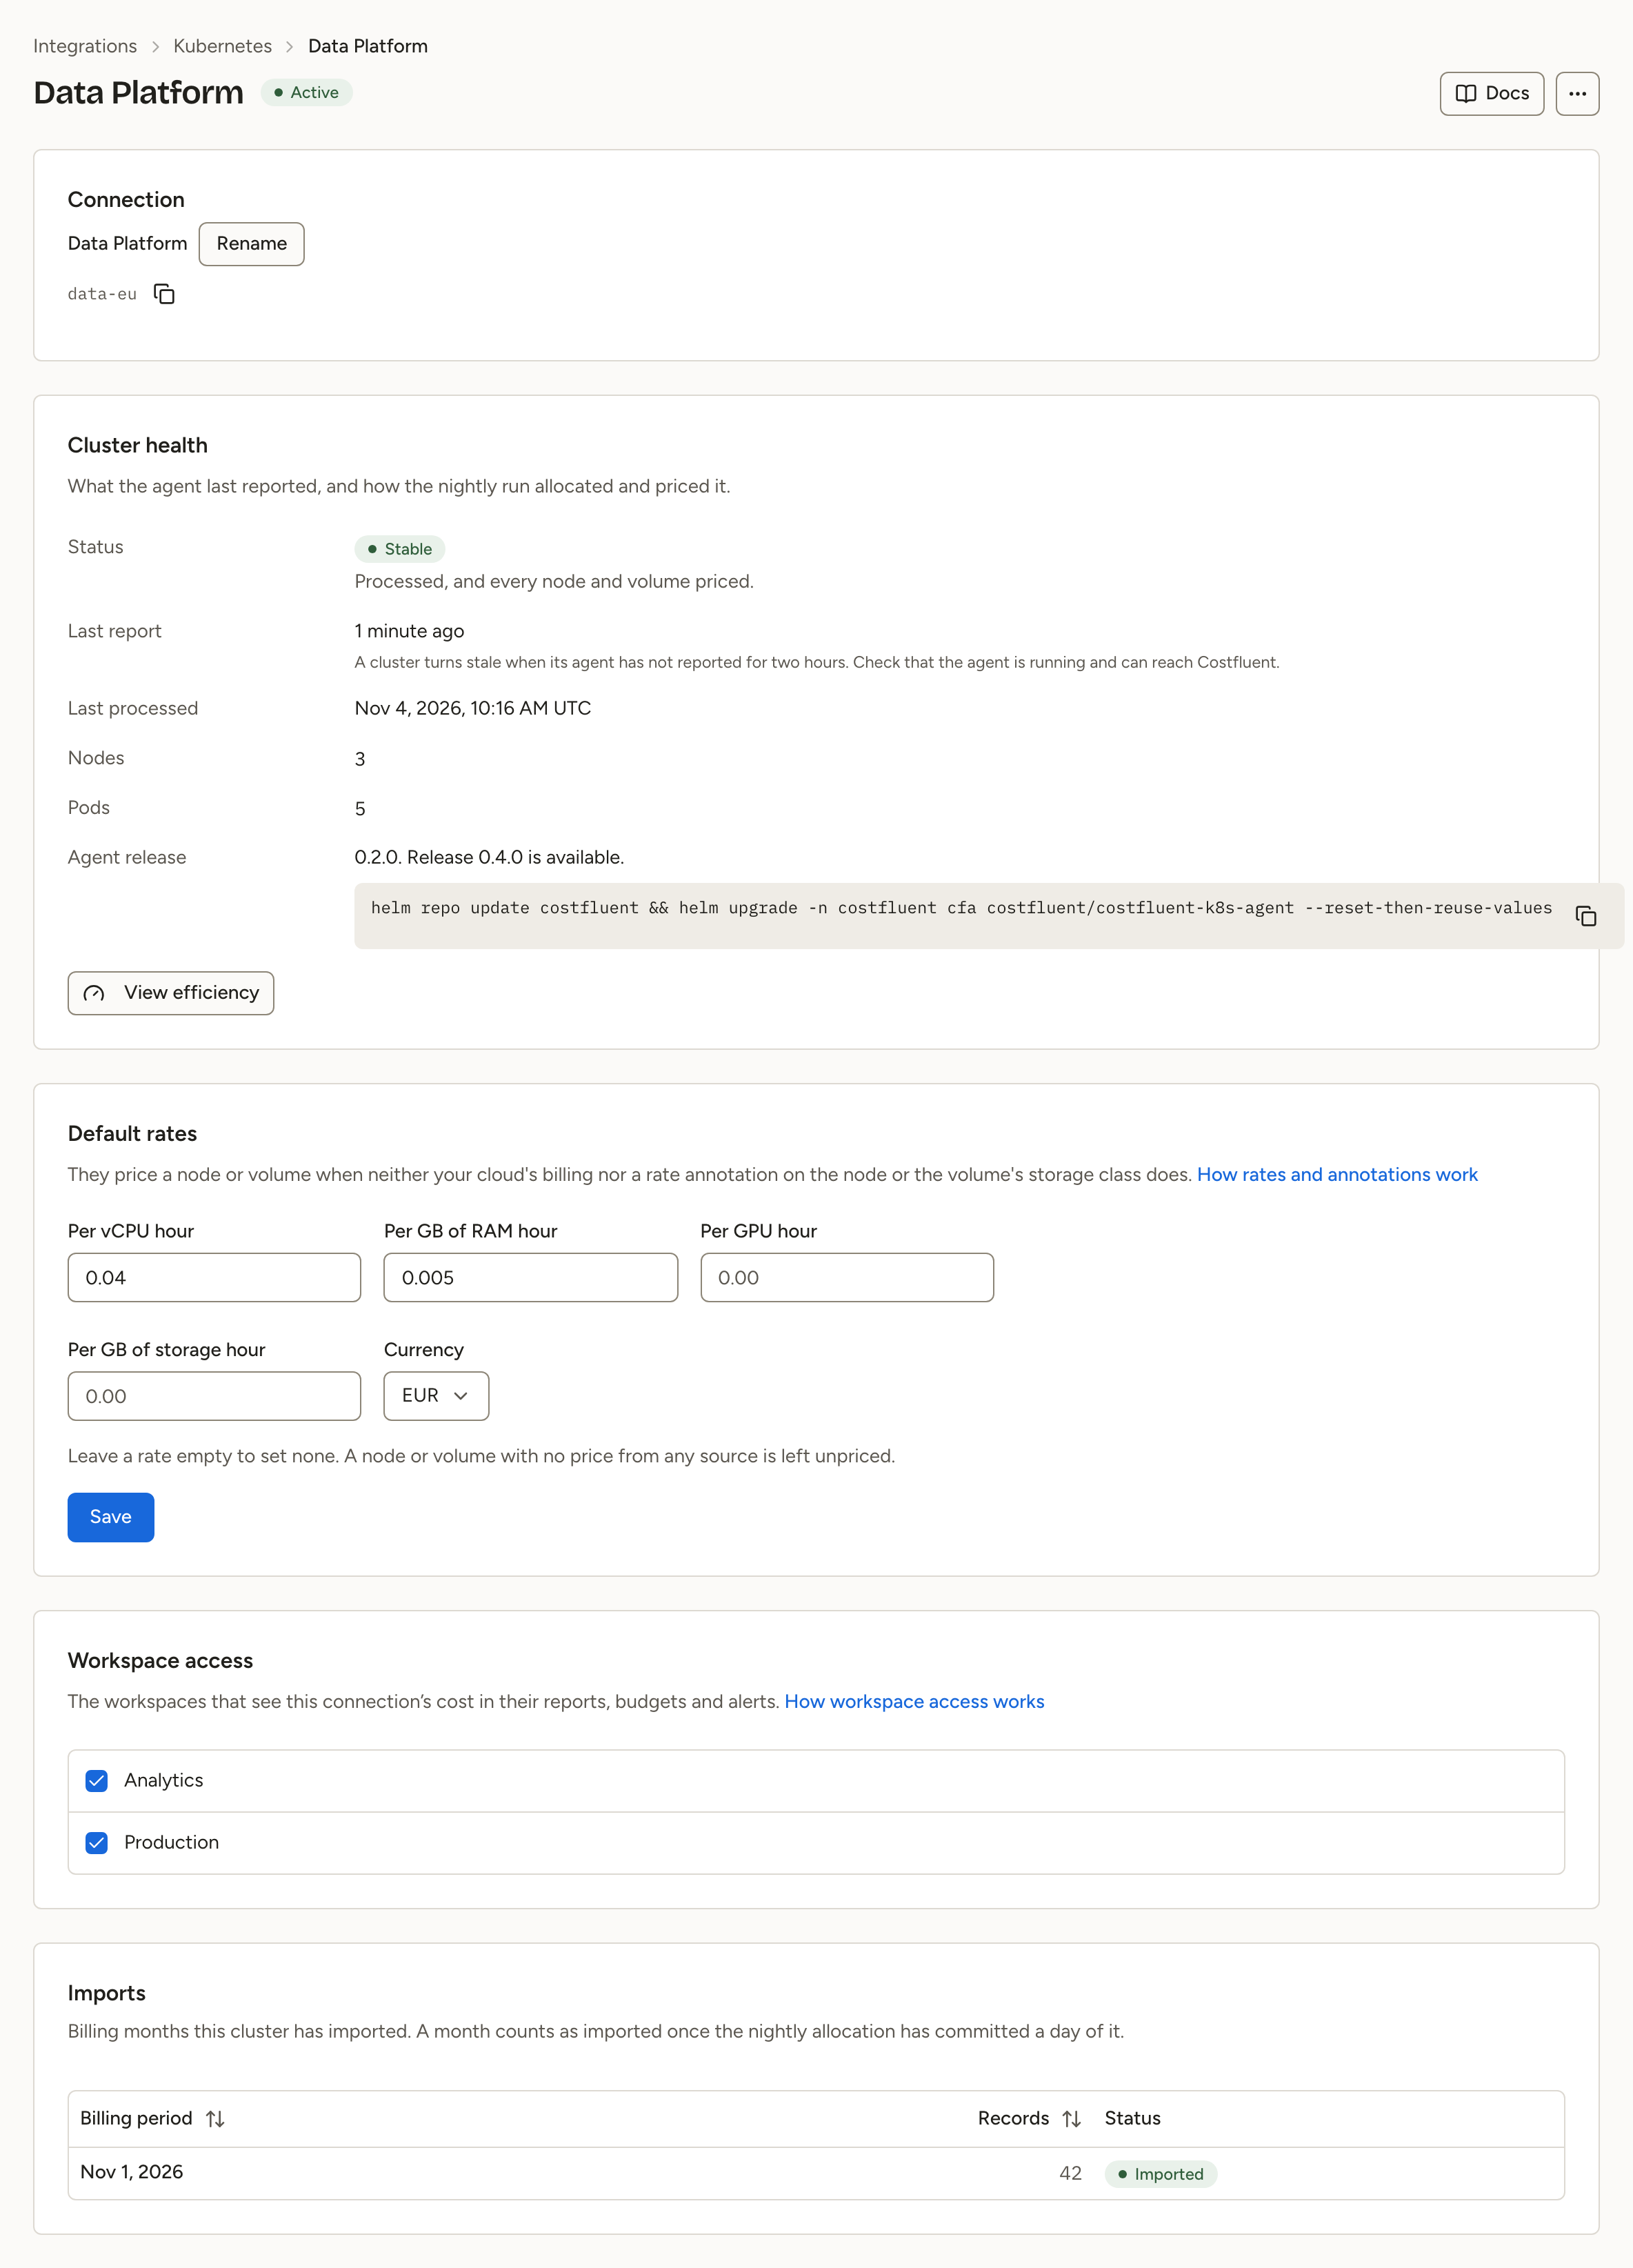
A cluster's cost appears only in the workspaces it feeds, and a new cluster feeds none. On the Manage tab, the Connections card lists the clusters, and its Workspaces column names the workspaces each cluster feeds; for a cluster that feeds none it warns "No workspace sees its cost", a link to the cluster's page. Select a cluster's name, or Manage on its row, to open its page:
- The header shows the cluster's name, its connection status and Docs, and, for Owners and integration owners, a menu with New token and Remove connection.
- Connection shows the cluster's name and its cluster ID, with Rename for Owners and integration owners.
- Cluster health shows its status and what it means, its last report, its last processing run, its nodes and pods, its agent release with the upgrade command when a newer one is out, and any nodes or volumes without a price, with Set default rates, which takes you to Default rates. A Pending, Stale or Warning status links Troubleshoot to its entry under Troubleshooting, and Pending shows the command that lists the agent's pod. While the current workspace reads the cluster, View efficiency opens Kubernetes efficiency filtered to it.
- Default rates holds the cluster's rates and currency (On-premises and custom rates).
- Workspace access has a checkbox for each workspace: tick the ones that should see the cluster's cost. Owners, and integration owners who can edit that workspace, can change it. Workspaces you cannot view are counted below the list.
- Imports lists each month from the one the cluster was added in. A month counts as imported once the nightly allocation has committed a day of it.
Each cluster has its own workspace access, so clusters of one organization can feed different workspaces.
Data and freshness
How costs are calculated
Each node's cost for the day is split into CPU, memory and, on GPU nodes, GPU. The calculation uses
container resource requests and measured usage to distribute cost to namespaces. The part of a
node's cost that remains unallocated is idle cost, and appears as the namespace
__idle__, which reports and filters show as Idle capacity.
A node's price comes from the first of these that has one:
- The compute usage an AWS, Azure or GCP connection in your organization bills for the node's machine, including CPU credits and licences billed with it.
- The node's own annotations, described below.
- The rates set for the cluster in Costfluent.
Data transfer, other services billed against the machine, credits, refunds, adjustments and tax are not part of a node's price and stay in the cloud's own reports.
A node none of them prices is left out and counted as unpriced on the cluster.
A GPU node's capacity, its pods' GPU requests and their usage in GPU-Hours count physical GPUs. Of a
node's price from its cloud bill, 95% is its GPUs'. From version 0.4.0 the agent reads each GPU
resource a node advertises, nvidia.com/gpu, nvidia.com/gpu.shared, the nvidia.com/mig-*
profiles and amd.com/gpu, and the labels the NVIDIA GPU Operator's GPU Feature Discovery writes on
the node (nvidia.com/mig.strategy, nvidia.com/gpu.product, nvidia.com/gpu.count,
nvidia.com/gpu.replicas and nvidia.com/gpu.slices.gi):
- MIG, single strategy: the devices appear as
nvidia.com/gpu, and each is its share of a GPU, which holds as many as its compute and memory allow. An A100 split into seven1g.5gbdevices is one GPU, and a pod requesting one device pays a seventh; an H100 holds four1g.20gb, a quarter each. - MIG, mixed strategy: a
nvidia.com/mig-<n>g.<m>gbdevice is itsncompute slices' share of a GPU, of seven on an A100, H100, H200 or B200 and four on an A30. Where a node's devices fill more GPUs by memory than by compute, those taking more of a GPU's memory than of its compute also pay for the compute slices their memory leaves no room for: four1g.20gbon an H100 pay a quarter each, as in single strategy, and sixteen3g.40gbtake eight H100s at half of one each. The node counts the GPUs itsnvidia.com/gpu.countlabel states, partitioned or not, never more than the devices it advertises and at least the GPUs its devices need: eight3g.40gbon a node labelled with eight H100s count eight GPUs, and what they leave unpartitioned is idle. - Time-slicing: each replica, as
nvidia.com/gpuor renamednvidia.com/gpu.shared, is onenvidia.com/gpu.replicasth of a GPU. amd.com/gpucounts whole GPUs.
A node without those labels, or with a GPU whose slices Costfluent does not know, counts each device
as a GPU; state its physical GPUs with an annotation (below). An earlier agent reports
nvidia.com/gpu alone, counted as before.
From agent version 0.4.0, each persistent volume's day is a Storage row of its own, in
GiB-Hours of its capacity, beside its nodes' rows and never inside them. A volume's price comes
from the first of these that has one:
- Every usage row an AWS, Azure or GCP connection in your organization bills for the volume's
disk on the day, capacity, provisioned IOPS and throughput included: an EBS volume by its
vol-id, which needs an AWS export with resource ids; an Azure managed disk by its resource id; a GCP persistent disk by its project and disk name, which only the detailed billing export carries. Snapshots are billed under their own ids and are not part of it. - Its storage class's rate annotation, described below.
- The cluster's default storage rate.
A volume none of them prices is left out and counted as unpriced on the cluster. The volume's cost goes to the pods that mounted its claim, by the seconds each mounted it; two pods mounting it at once share it. What no pod mounted stays with the claim's namespace, with no pod, because the claim was made for it. A volume no claim holds, such as a Released or Available one, is idle cost. The agent's own buffer volume is a claim too, and shows as storage cost in the agent's namespace.
Costfluent processes each cluster once a night, at 04:30 UTC, for the previous day. Cost therefore appears the morning after the agent is installed, while the Kubernetes page shows the latest report within minutes. A day with a node on an AWS, Azure or GCP machine, or a volume on one of their disks, is processed once more two days later, when that cloud's billing for the day has usually landed in full, and its figures can change then.
In Cost Reports, group or filter by Cluster and Namespace, use pod labels as tags named
k8s:label:<key>, node labels as tags named k8s:node_label:<key>, a volume's claim and storage
class as k8s:pvc and k8s:storage_class, and claim labels as k8s:pvc_label:<key>. Kubernetes
efficiency measures CPU and memory only: Storage rows add to neither its cost nor its idle cost.
On-premises and custom rates
For nodes without cloud billing, such as on-premises or bare-metal clusters, open the cluster's page and, on the Default rates card, set its rates Per vCPU hour, Per GB of RAM hour, Per GPU hour and Per GB of storage hour, and their Currency, then select Save. Owners and integration owners can change them; everyone else sees them read-only. To price individual nodes differently, annotate them:
Code
Annotation rates are read in the cluster's currency and take precedence over the cluster's rates. A node with any rate annotation is priced from its annotations alone: a resource it has no annotation for is not filled in from the cluster's rates.
Write each rate as a plain decimal number with a point, such as 0.021. Any other value, such as
0,021, 1,000.5, 1.5e3 or a negative rate, leaves the node unpriced and counted as unpriced on
the cluster, rather than read as a different number or filled in from the cluster's rates. An empty
annotation counts as no annotation.
On a GPU node whose labels do not say how its devices map onto physical GPUs, state how many it has:
Code
The count is a whole number above zero, and any other value is ignored. It takes precedence over the labels, applies only to a node that advertises a GPU, and on a node without the labels makes each of its devices an equal share of those GPUs.
A volume whose disk no cloud bills, such as one of a Ceph, Longhorn or local-path class, or a
file share, is priced by its storage class's rate per GB of capacity hour, before the cluster's
default storage rate:
Code
The rate is read in the cluster's currency, written as a plain decimal like the node rates, and any other value leaves the class's volumes unpriced.
How totals count a cluster
A cluster's cost is the cost of its nodes, which the cloud connection that pays for them already reports. So a total counts that cost once: a Cost Report or cost alert over a workspace that holds both sources leaves the cluster's rows out, and Costfluent does not count Kubernetes cost toward tracked spend.
The cluster's rows count when the report asks for Kubernetes: a filter or grouping by provider,
cluster, namespace or a k8s: tag, or a Public API query or cost alert that names the cluster's
connection.
Grouped by namespace, the report shows the allocation; grouped by provider, it shows the cluster
beside the cloud that pays for it, so that total holds the nodes twice.
Reporting dimensions
What each group-by dimension of a cost report holds for a cluster, and the field of the agent's report it comes from. A cluster's rows count only when the report asks for Kubernetes (How totals count a cluster).
| Dimension | For Kubernetes | From |
|---|---|---|
| Provider | kubernetes | The agent |
| Provider name | Kubernetes | |
| Sub-account | Never filled | |
| Service | CPU, Memory or GPU: one row per container and category; Storage: one row per volume and pod mounting it | The calculation (How costs are calculated) |
| Region | The node's region; none on a Storage row, as a volume has no node | nodes[].region |
| Resource | The pod's name; the node's name on an idle row; the volume's name on a Storage row | pods[].name, nodes[].name, volumes[].name |
| Charge category | Always Usage | |
| Tag | k8s:label:<key> for every pod and namespace label (a pod label wins over a namespace label), and k8s:cluster, k8s:namespace, k8s:node, k8s:pod, k8s:container, k8s:controller_kind, k8s:controller and k8s:category on every row; k8s:node_label:<key> for every label of the row's node, on its idle rows too, except the hostname, instance type, region and zone labels, which the row already states, and the deprecated beta aliases; on a Storage row, no k8s:node or k8s:container, but k8s:storage_class, k8s:pvc unless the volume is idle, and k8s:pvc_label:<key> for every label of its claim | pods[].labels, pods[].namespace_labels, nodes[].labels, volumes[].storage_class, volumes[].claim_name, volumes[].claim_labels, the row's own fields |
| Segment | Your allocation rules | Segments and allocation rules |
| Cluster | The cluster ID the agent was installed with, not its display name | cluster_id |
| Namespace | The pod's namespace, or a volume's claim's; __idle__, shown as Idle capacity, for a node's unallocated cost and a volume no claim holds | pods[].namespace, volumes[].claim_namespace |
| Virtual tag | Your virtual tag rules | Virtual tags |
The k8s: keys Costfluent writes on every row, from k8s:cluster to k8s:category, and
k8s:pvc and k8s:storage_class, group and filter like any tag but do not make a row tagged: for
Tagged, a cluster's row is tagged only when it carries a k8s:label:<key>,
k8s:node_label:<key> or k8s:pvc_label:<key> tag. Tag coverage leaves a cluster's
rows out altogether (Tags and tag coverage).
Update or disconnect
Update the agent
The Manage tab shows each cluster's agent version. When an agent is older than the one the
newest chart installs, its row reads Update available with the latest version, and Update the
agent under the table shows the command that updates it. Run it with that cluster as kubectl's
current context; its token and settings stay as they are, and settings the new chart adds take
their defaults. It needs Helm 3.14 or newer, for --reset-then-reuse-values; an older Helm stops
with an unknown flag. Pinned to the chart this page documents:
Code
A GitOps install updates through its manifest instead (GitOps with Argo CD or Flux).
Costfluent learns the newest agent from the chart repository within six hours of a chart release. While it cannot read the chart repository, no cluster is marked.
Rotate the token
A cluster token does not expire. It stops working when it is revoked, and when the account that minted it is disabled or deleted. Replace it whenever it may have leaked, and before that account leaves.
-
On the Manage tab, choose New token in the cluster's row menu, or in the menu on the cluster's page. The token it shows works beside the old one until you revoke the old one.
-
Give it to the agent. With
agent.token, upgrade the release with the new value; the chart rewrites its Secret and rolls the agent pod:CodeWith
agent.secret, replace the token in that Secret and restart the agent, which reads its token only when it starts:Code -
Once the agent's log shows a clean start, open Settings, then API tokens, and choose Revoke token on the old token's row.
Disconnect
A Helm install is removed with these commands; a GitOps install through its controller (GitOps with Argo CD or Flux).
Code
The cluster turns Stale two hours later and its past cost stays in Cost Reports. Remove it with
Remove connection in its row menu on the Manage tab, or in the menu on its page, and confirm
with Remove in the Remove connection dialog, which shows the uninstall command and names the
workspaces the cluster feeds. Removing a cluster erases the cost
allocated to its namespaces and removes it from every workspace, and this cannot be undone. An agent still running for a removed
cluster is refused with 410, and the cluster's tokens stop working with it.
Troubleshooting
Cluster statuses
| Status | Meaning |
|---|---|
| Pending | The cluster was added, and no report has arrived yet. Check that the agent is installed with this cluster's token and that its pod is running. |
| Importing | The cluster has reported, and its first day has not been processed yet. |
| Stable | Reports arrive and each day is processed. |
| Stale | No report for two hours. Check that the agent pod is running and can reach Costfluent. |
| Warning | Some nodes or persistent volumes have no price, processing a day failed, or a day was grouped. The line under the status, Last processing run:, says which. A cluster whose agent could not read some nodes shows Warning too, and its health card says on how many (Common errors). A volume of a class no cloud bills is priced once its storage class has a rate annotation or the cluster a default storage rate. |
Under Settings, Integrations, a cluster's connection reads Pending until the first
nightly run processes its cost, then Active, with that run as its Last sync; each later run
that processes a day moves it. Once it is Active, a cluster whose agent stops reporting is
announced a day after its last report, and once more at three days and at least two days after the
first notice, while the agent still holds the reports it could not send (96 hours): by in-app
notice, email, your organization's channels and the connection_stale webhook, linking to the
clusters page. A report clears the notice. A night that fails while the agent reports is not
announced; the cluster shows Warning with the error.
Stable, but no cost in reports
A cluster can be Stable while a workspace's reports show none of its cost:
- The cluster feeds no workspace, or not this one. The Workspaces column on the Manage tab names the workspaces it feeds, and reads "No workspace sees its cost" for a cluster that feeds none. Tick the workspace under Workspace access on the cluster's page (Choose which workspaces see a cluster).
- The workspace has switched the cluster off. Under Settings, then Workspace providers, the cluster's Enabled switch is off; switch it on (Manage connections).
- The report does not ask for Kubernetes. In a workspace that also reads the cloud connection paying for the cluster's nodes, a total leaves the cluster's rows out so that the nodes count once. Filter or group the report by provider, cluster or namespace to see them (How totals count a cluster).
Common errors
The agent logs every refused upload with the reason. The common ones:
- 401, 403, or "is not a cluster token". The token is wrong, revoked, or not this cluster's own token; an organization API token is refused. The agent checks its token when it starts and exits with this reason, so the pod restarts instead of reporting ready; a token refused later stops the sending until the agent restarts. Reports stay buffered: replace the token as in Rotate the token to recover them.
- "is not the cluster the API token belongs to".
agent.clusterIDnames another cluster than the token's. Removeagent.clusterID, or install that cluster's token. - 400. The report was refused as invalid, and the log names the reason. When the reason is
more nodes or pods than one report may carry, the cluster is larger than Costfluent collects;
contact support. When it is that
window_endis in the future, the node's clock runs more than five minutes ahead, and agent versions up to 0.2.1 drop that report: fix the node's time sync (NTP). When it is thatwindow_startis older than the days Costfluent still processes, the window began more than six days ago, which an agent keeping reports for 96 hours reaches only when the node's clock runs days behind; the agent drops that report: fix the node's time sync (NTP). Otherwise, upgrade the agent. - 409. Another agent already reports this cluster for an overlapping window: run one agent per cluster, each with its own cluster's token. When the log says instead that the day already holds 1,440 reports, the agent restarted hundreds of times that day: find why its pod restarts. The agent drops the report either way; a day at 1,440 reports is processed with those it keeps.
- 410. The cluster was deleted in Costfluent. Uninstall the agent, or add the cluster again and install its new token.
- 413. A report was too large. Agent versions up to 0.2.1 back off and retry it; limit
agent.allowedLabelsif it persists. - 429. The agent keeps the report and sends it again. When the log says the organization's clusters already sent 1 GiB of compressed reports today, the report is accepted after midnight UTC, unless the agent's buffer drops it first. Otherwise Costfluent was busy with other reports, and the agent sends it again shortly.
- No usage, or fewer nodes than the cluster has. The agent could not read some kubelets. It
leaves a node it cannot read, and its pods, out of the report rather than count them as unused,
and from chart 0.4.0 it reports how many nodes it could not read and why: the cluster turns
Warning, and its Cluster health card says on how many of its nodes usage is unreadable,
with the fix for each reason. The agent's log names each node and reason, as "kubelet scrape
failed" (
kubectl -n costfluent logs -l app.kubernetes.io/instance=cfa):tls: the kubelets serve certificates the agent cannot verify, as Talos, kubeadm and kind do by default. Have the cluster CA sign them, the secure fix, or setagent.disableKubeTLSverify=true(Kubelet certificates).unreachable: the agent found no address for the node or could not connect to port 10250, as on AKS, where kubelets are often not reachable at their default address. Setagent.nodeAddressTypes=InternalIP, and allow port 10250 where egress is denied by default (Default-deny egress).unauthorized: the kubelet, or the API server issuing its token, refused the agent's kubelet account. Check that its ClusterRole grantsgetonnodes/metrics, that the agent may create that account's token, and that the kubelets authenticate tokens by webhook.other: the agent's log names the error.
- Pod Pending, or the install stops with "no default StorageClass". No StorageClass provisions
the agent's volume claim, so the pod is never scheduled and logs nothing; from chart 0.3.0 the
install stops before creating anything. Set
persist.storageClassNameto one of the cluster's classes (kubectl get storageclass), or install withpersist=null. A pending release keeps its claim: uninstall it and delete the claim (kubectl -n costfluent delete pvc -l app.kubernetes.io/instance=cfa) before installing again. - The install fails with "context deadline exceeded" or a timeout. The install waits until the
agent's pod is ready, five minutes by default. A slow image pull can take longer: run the same
command again, which picks the release up where it stopped. When the pod still does not become
ready,
kubectl -n costfluent describe pod -l app.kubernetes.io/instance=cfanames why: an image that cannot be pulled, a pod security or quota refusal, or a node selector that matches no node.